Not measurably, on data we collected on 26 September 2026, when we checked every software brand in our AI Software Index for an llms.txt file: 573 of the 1,150 we could reach publish one, almost exactly half, and across 123 categories those brands were not reliably recommended by ChatGPT or Gemini more often than rivals without one. They were no more likely to be named first, either. An earlier test on the 50 most-cited domains in our own corpus found the same thing. Every figure, including the first-pick comparison, is in the published dataset.
Disclosure: GetIntel makes a free llms.txt generator and llms.txt checker, so the commercial incentive runs towards telling you the file works. Both datasets behind this article are published so you can check the numbers rather than trust them.
Does llms.txt actually work?
On the outcome that matters, whether AI assistants recommend you, we could not find an effect. We requested https://<domain>/llms.txt from all 1,224 brand domains in the AI Software Index, the study of which software ChatGPT and Gemini recommend across 126 categories, measured on 9,978 buyer questions in August 2026. A domain counted as having a file only if the final response was a 200, the path ended in .txt, the body was not an HTML page and it contained a markdown heading or link. That last test matters: 60 sites answered with their HTML 404 page and a 200 status, which a naive check would count as a file. 74 domains blocked the request or timed out and are left out.
| Result | Domains |
|---|---|
| Publish an llms.txt | 573 |
| No llms.txt | 577 |
| Could not check (blocked or timed out) | 74 |
Checked 26 September 2026, 1,224 brand domains from the AI Software Index.
Then we compared, inside each category, how often AI mentioned the brands with a file against the brands without one. Comparing within a category matters, because adoption varies enormously by category, from 11 of 12 e-commerce platforms and 12 of 15 website builders to 2 of 14 cloud storage tools and 1 of 10 whiteboard tools, and those categories differ in everything else too.
| Within-category comparison | Categories |
|---|---|
| Brands with a file mentioned more (by over 2 points) | 64 |
| Brands with a file mentioned less (by over 2 points) | 49 |
| Within 2 points | 10 |
123 categories with at least two brands on each side. Median gap: 2.6 points in mention rate. Median gap in first-pick rate: 0.
A 64 to 49 split looks like a small edge, but a coin flip lands at least that far from even about one time in five (a two-sided sign test gives p = 0.19), so it is not a difference we can rely on. The first-pick rate, how often a brand is the one an answer recommends first, shows no gap at all. And among the brand named first most often in each category, 71 of 126 (56%) publish a file, against 50% of brands overall: again inside what chance produces. The pattern is consistent with the obvious confound, that larger and more active companies both publish more files and get recommended more, rather than with the file doing the work.
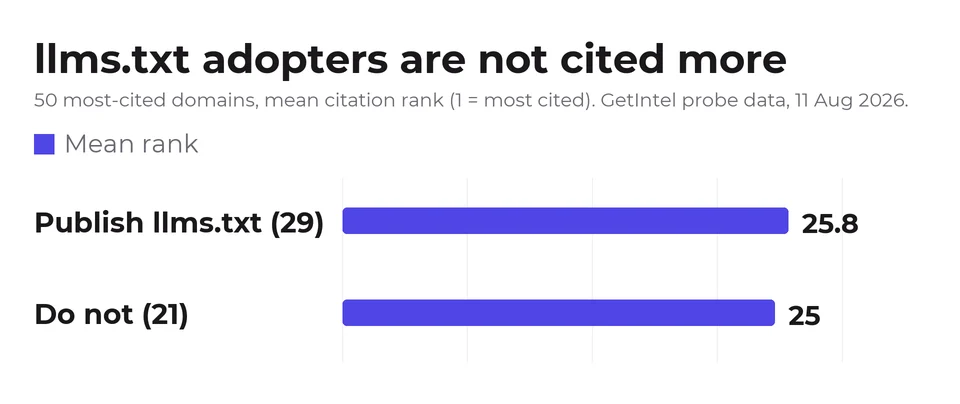
The earlier test points the same way. On 11 August 2026 we checked the 50 domains AI engines cited most often in our own corpus of 47,093 citations: the 29 that publish an llms.txt sat at a mean citation rank of 25.8, against 25.0 for the 21 that do not, where 1 is the most cited. The two most-cited domains of all, YouTube and Reddit, have no file.
Which AI crawlers read llms.txt?
As of 26 September 2026, no major AI company has said its assistant uses llms.txt when it answers a question, and Google has said the opposite. Its guidance on AI features in Search, last updated 10 December 2025, says: "You don't need to create new machine readable files, AI text files, or markup to appear in these features." OpenAI, Anthropic and Perplexity have made no public commitment either way.
Our own logs cannot settle it yet, and the reason is worth knowing if you run the same kind of setup. Between 17 August and 26 September 2026, Cloudflare logged 6,939 visits to getintel.ai from AI assistants and their search crawlers: 2,624 from ChatGPT-User, 2,179 from PerplexityBot, 1,930 from OAI-SearchBot, 203 from Claude-User and 3 from Gemini. But the per-page crawler analytics we use skipped static files, and /llms.txt was on that skip list, while the Cloudflare summary lists only the most-visited pages, so requests for the file itself were never broken out. We removed it from the skip list on 26 September 2026. We will publish what the crawlers actually requested, by bot, on 10 October 2026.
What the logs do show is that the crawlers read ordinary pages heavily. ChatGPT-User, the agent that fetches a page while writing an answer, made 2,624 requests in six weeks, spread across 173 pages. A file that no engine has committed to reading is a thin substitute for pages those agents already fetch.
Should you add one anyway?
Add an llms.txt if it takes you ten minutes, and skip it if it would take the place of anything else. An llms.txt costs almost nothing to publish and cannot hurt, and the proposal was written for a narrower job than search: helping an AI tool that a person points at a site, such as a coding assistant reading documentation, find the pages that matter. What it has not shown, in either of our tests, is any lift in how often AI assistants recommend or cite you. The work that moves that is elsewhere: in our source tracking, 91% of the citations in AI answers about our own category went to third-party sites such as Reddit, YouTube and review roundups, not to vendors' own pages. The same pattern held when we tested schema: FAQ schema showed no citation lift across 615 pages, and when we tested the AI access checklist on 37 cited pages, not one blocked an AI crawler, so the checklist items are rarely what separates cited pages from the rest. For shipping the file and schema through a coding agent, see shipping llms.txt and schema fixes.
How to write an llms.txt
The llms.txt proposal sets a simple order: a # Name title on the first line, an optional > one-line summary, a few sentences of plain description with no headings, and then ## sections that are lists of links in the form - [Page name](URL): what is on it. Keep headings for link lists only; descriptive text belongs above the first ##.
What belongs in it is a factual description of what you are, written the way you would explain the product to a smart stranger ("X is a tool that does Y for Z"), and a curated list of five to fifteen key pages (homepage, pricing, docs, your main use-case and comparison pages), each with a one-line note. A plain sentence on who the product is for helps, because it is the part a model can lift almost directly.
The common mistakes are listing every page on the site, which buries the ten that matter; repeating keywords, which makes the summary less accurate, not more visible; and writing it once and never updating it, which feeds any reader an outdated description of your own product. The llms.txt generator builds the file from your sitemap in this layout, and the llms.txt checker fetches your live file and checks its structure. For a one-line definition, see what llms.txt is.
What this study cannot tell you
This llms.txt study shows association, not cause, and a small effect could hide inside it. The files were checked in September while the recommendations were measured in August, so some brands will have added a file after the answers were collected; if the file helped, that would dilute the gap rather than create one. Mention rate is a coarse outcome: a file could change which page an engine cites without changing whether it names you, and neither test measures that. And the index covers ChatGPT and Gemini, not Claude or Perplexity.
How we checked
The adoption scan requested /llms.txt from 1,224 domains on 26 September 2026 with a 12-second timeout, following redirects, and counted a file only on a 200 response, a .txt path, a non-HTML body and at least one markdown heading or link. Recommendation rates come from the AI Software Index. Both are in the published llms.txt adoption dataset, with every domain's result and every category's comparison. The August citation test is in its own dataset. Crawler counts come from Cloudflare's verified bot logs for getintel.ai.